>_ ANALYSIS
Sparse overlap is not a nuisance variable in judge validation; it is the decision variable
When annotation budgets are tight, the risk is not only noisy agreement scores. The paper by Junxuan Li, Arko Mukherjee and Soumyabrata Pal argues that sparse overlap can flip the deployment decision itself: at 5% pairwise overlap, wrong-decision rates reach 25%, and the chance of picking the wrong best judge among ten
When annotation budgets are tight, the risk is not only noisy agreement scores. The paper by Junxuan Li, Arko Mukherjee and Soumyabrata Pal argues that sparse overlap can flip the deployment decision itself: at 5% pairwise overlap, wrong-decision rates reach 25%, and the chance of picking the wrong best judge among ten candidates rises to 65%.
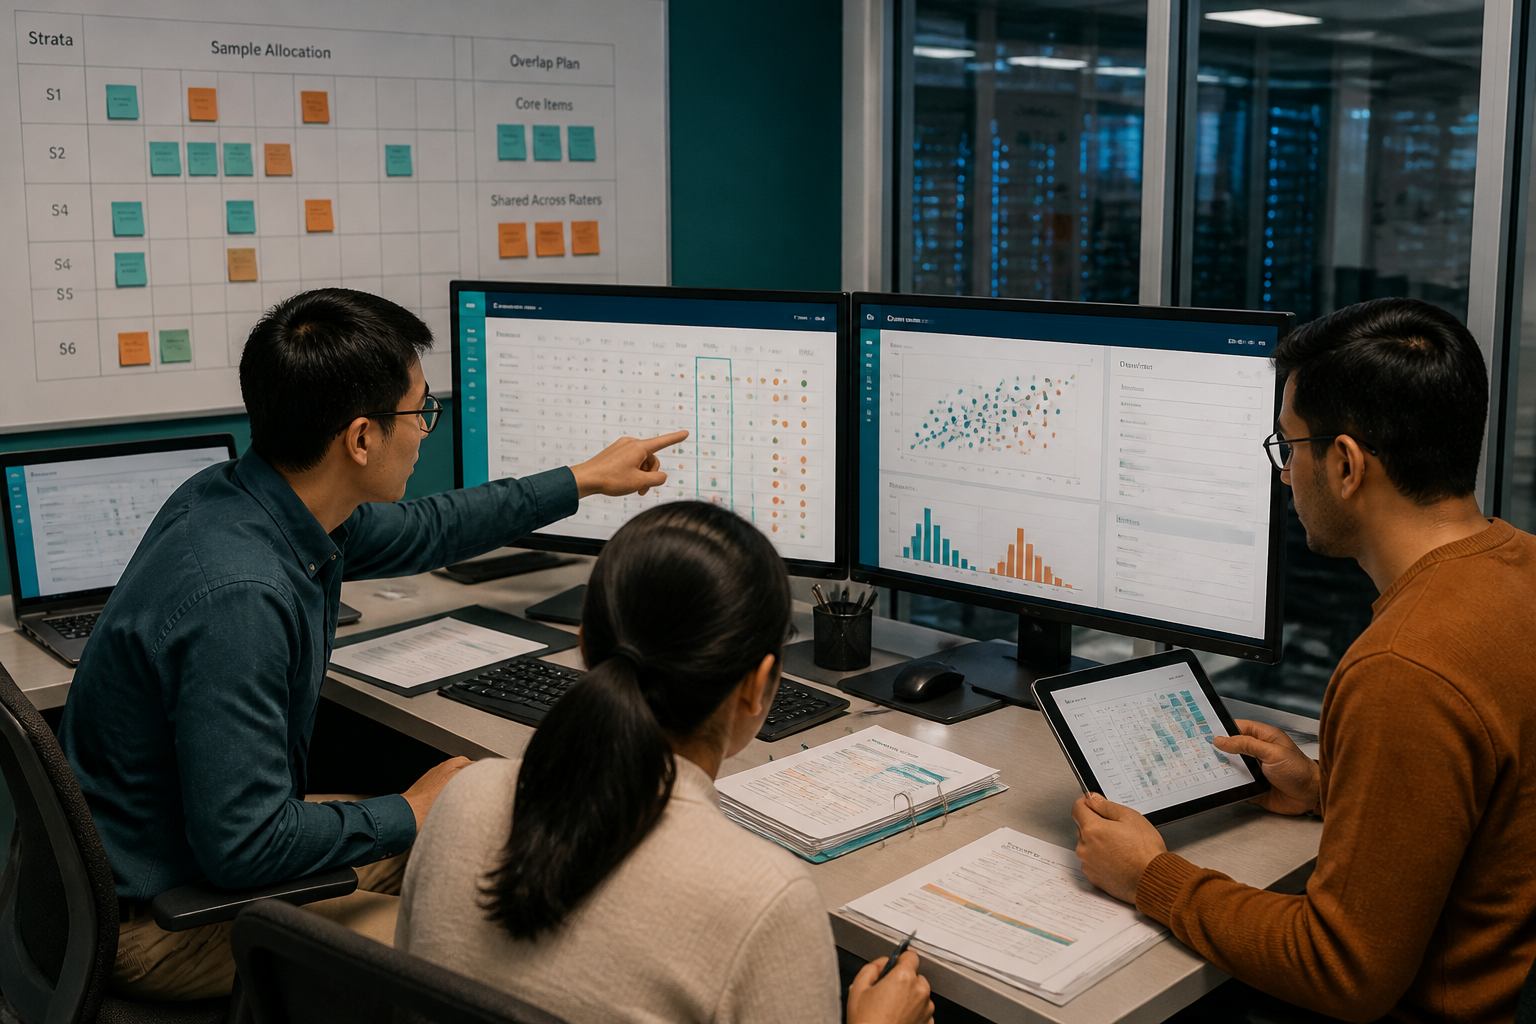
That is the practical shift. The authors are not saying every sparse study fails; they are saying the usual validation workflow can look more precise than it is when too few items are shared across raters. In their framing, overlap is the first-order lever, while the choice of agreement coefficient is secondary. They also derive a minimum-overlap rule, with ρ ≥ 0.25 sufficient for non-borderline judges, and show that a zero-cost stratified design can halve false-rejection rates when strata are informative.
The mechanism is straightforward. If shared items are too few, agreement estimates become unstable enough to mis-rank judges or reject a usable one. If overlap is concentrated badly, the ceiling estimate itself can be distorted. The paper’s contribution is to turn that qualitative concern into a design problem: how much overlap is enough, and how should the limited labels be allocated before data collection starts.
A strong alternative explanation is that the headline error rates depend heavily on the paper’s validation setup and the ten judges it tested. The authors themselves do not establish universal thresholds; they validate across four evaluation matrices spanning visual assessment, causal reasoning and summarization, but external replication is not shown here. That matters because “25% at 5% overlap” should be read as evidence of fragility, not a universal constant.
Still, the operational implication is hard to ignore. If you are deciding whether a judge is good enough, sparse overlap should not be treated as a minor sampling inconvenience. It can change the answer. The most useful near-term check is whether the minimum-overlap formula and the stratified allocation gain hold on other judge tasks with different label skews. If they do, validation teams will need to budget for overlap as a gating input, not an afterthought.
Source: https://arxiv.org/abs/2609.31857